Lava lamp v1 · OpenCode · run 44255a11 · 09.11.2026 21:19 Tallinn
Muse Ember
Medium effortWorks
8 of 8 checks passed. All 5 blocker checks passed.
What it built: 3 captures
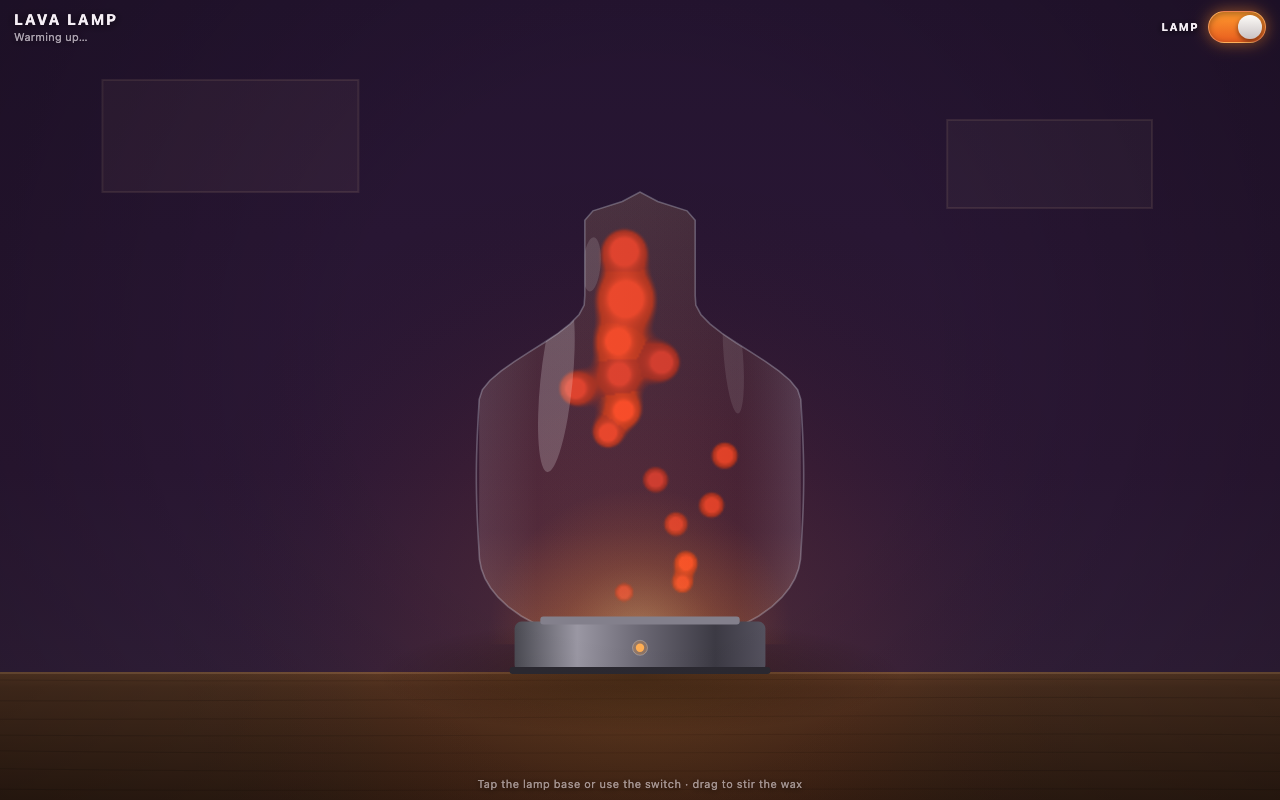
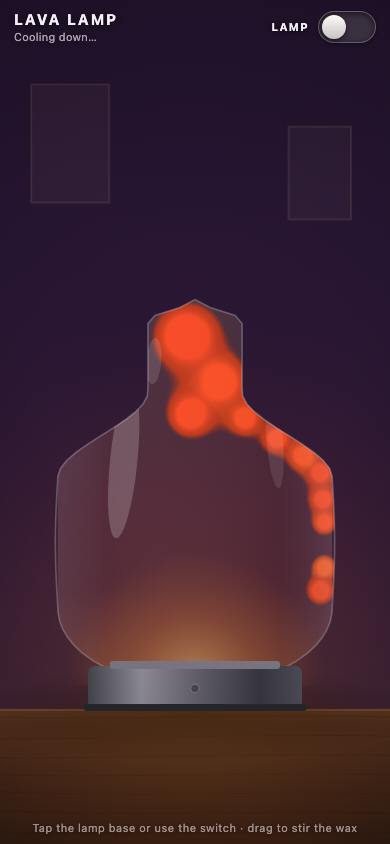
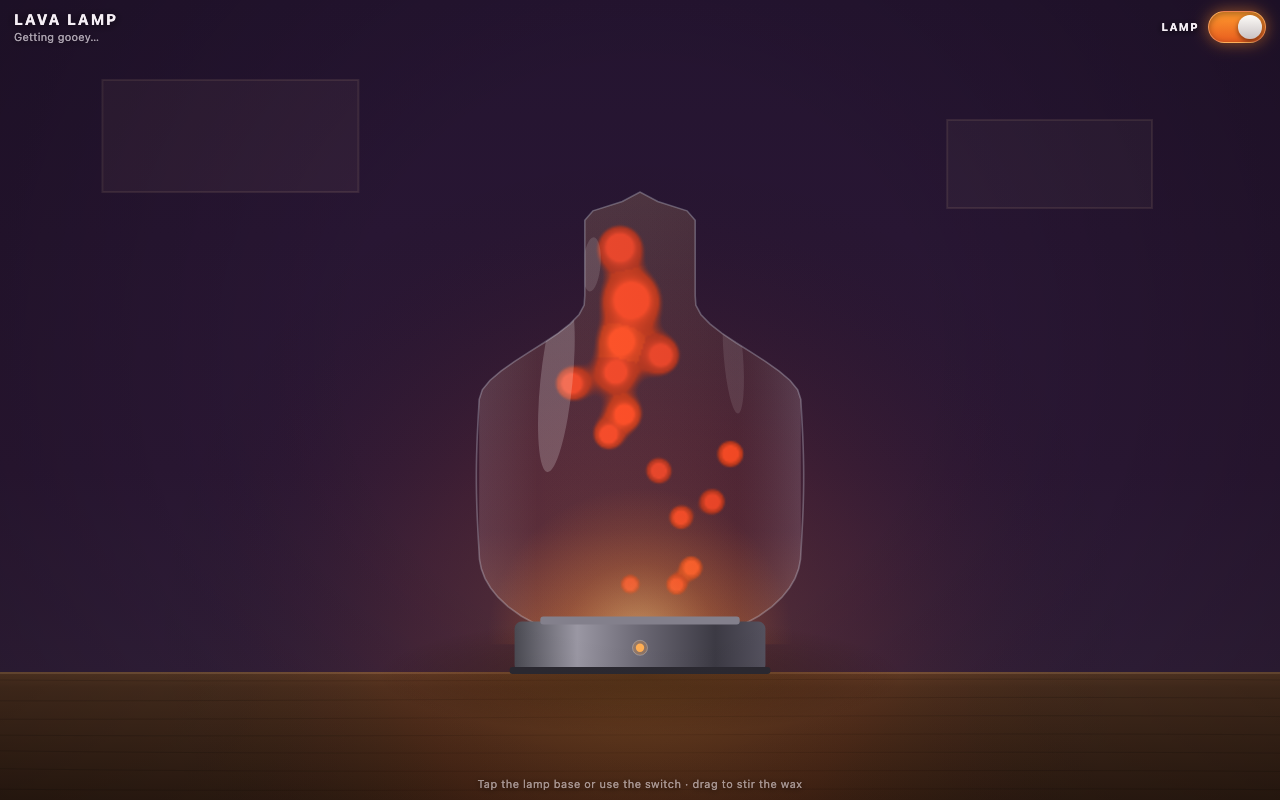
Build time
32.2 s
Fastest of 15 models at medium effort. Wall time, start to graded: 1m 30s.
Output tokens
14,177
9th fewest of 15 models at medium effort.
Output speed
440 tok/s
Highest of 15 models at medium effort.
API cost
$0.01
Computed from the run’s token counts at list prices, not a charge.
Along the row
Muse Ember at every effort.
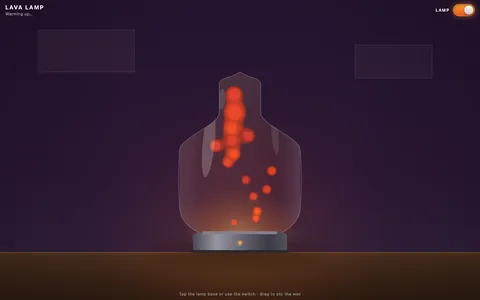
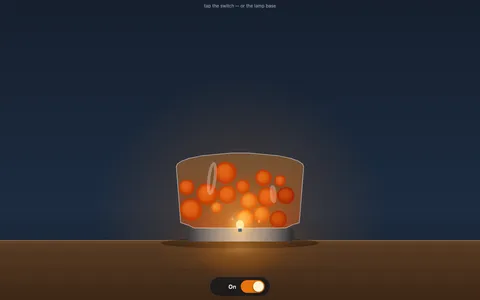
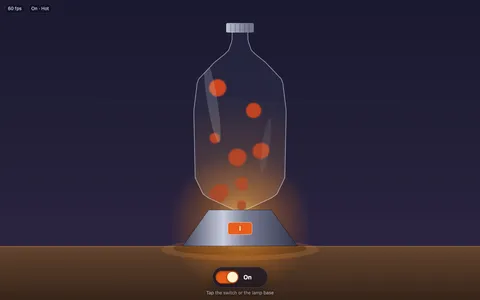
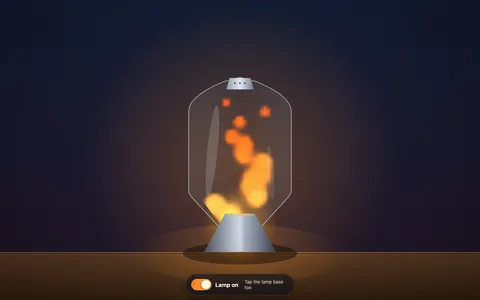
Down the column
Other models at medium effort.
Fastest median first · this run: 32.2 s
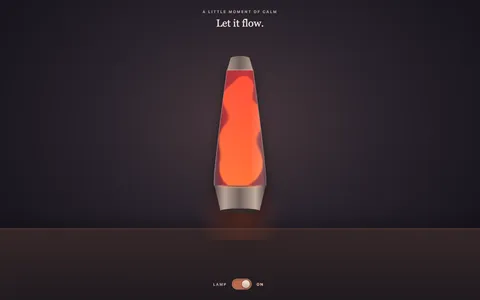 GPT-6.1 Terra47.9 s
Works
1.5× slower than this run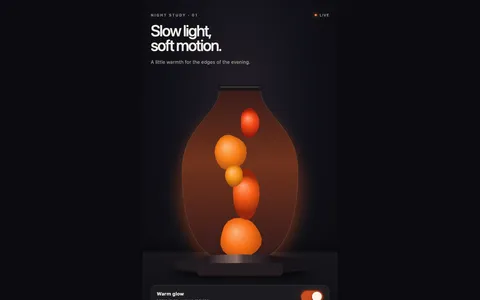 GPT-5.6 Luna59.1 s
Works
1.8× slower than this run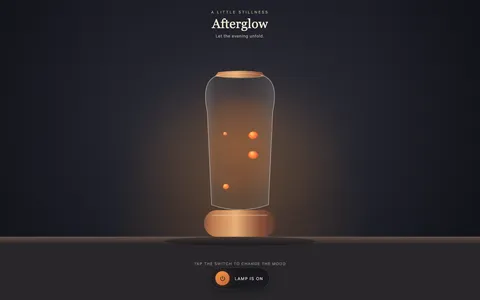 GPT-6 Luna1m 21s
Works
2.5× slower than this run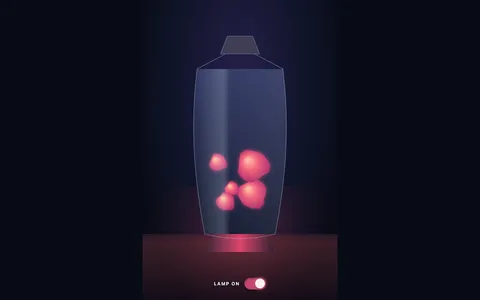 GPT-5.6 Terra1m 48s
Works
3.4× slower than this run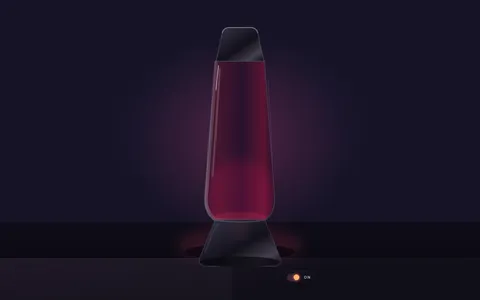 GPT-5.6 Sol2m 20s
Fails
4.4× slower than this run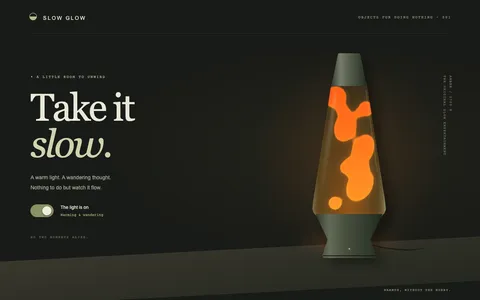 GPT-6 Astra4m 15s
Works
7.9× slower than this run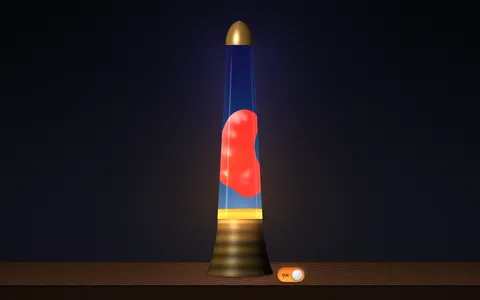 Claude Sonnet 5.54m 44s
Works
8.8× slower than this run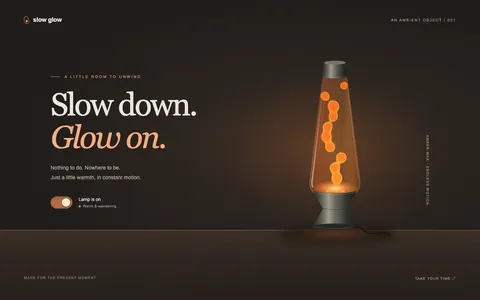 GPT-6.1 Sol4m 52s
Works
9.0× slower than this run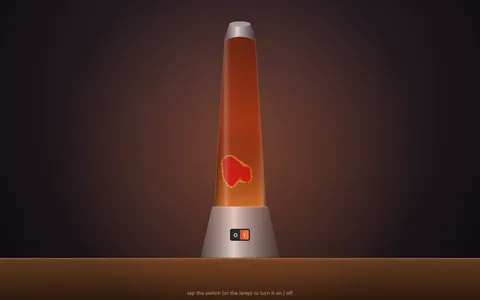 Claude Fable 5.14m 53s
Works
9.1× slower than this run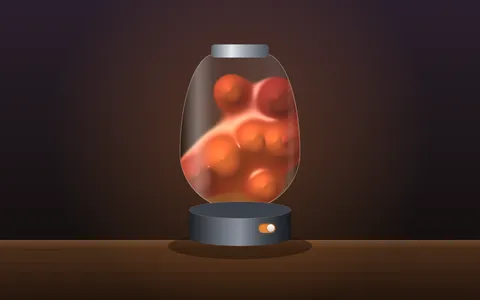 Claude Haiku 5.55m 06s
Works
9.5× slower than this run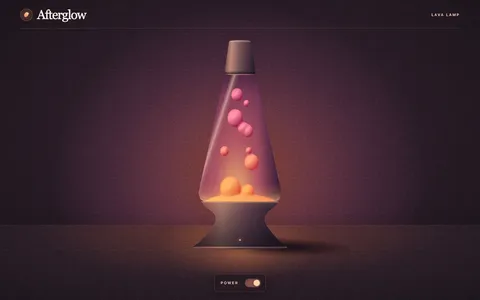 GPT-6.2 Sol7m 02s
Works
13.1× slower than this run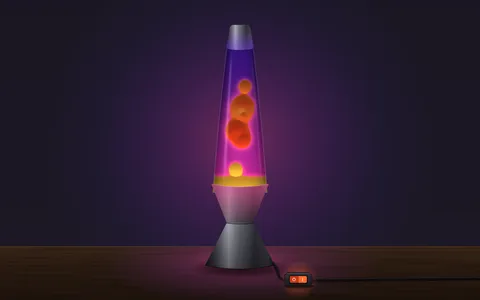 Claude Fable 5.27m 47s
Works
14.5× slower than this run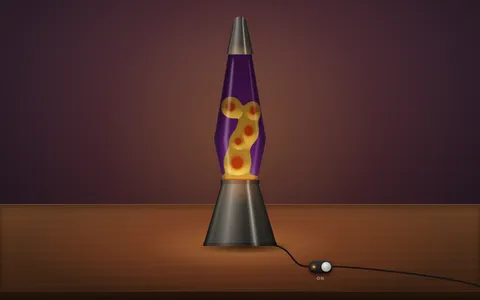 Claude Opus 5.58m 56s
Works
16.6× slower than this run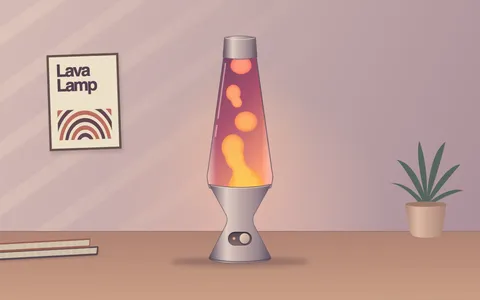 GPT-6.2 Astra9m 42s
Works
18.1× slower than this run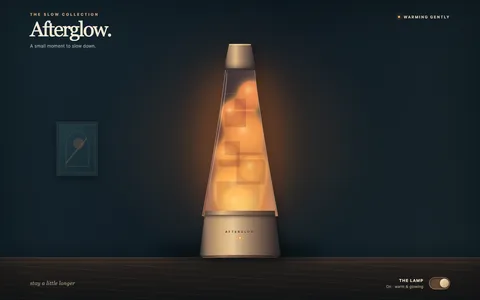 GPT-6 Sol—
Works
Hidden checks
8 of 8 checks passed.
- Self-contained index.html is presentblocker
- Visible page contentblocker
- Visible autonomous animationblocker
- Accessible on/off controlextra
- 390 px mobile layout has no horizontal overflowextra
- Local animation frame performanceextra
- No browser errorsblocker
- No attempted external or linked-resource requestsblocker
It works when every blocker passes. How it looks is reviewed blind: pending.
Run details
- Video (video): not published, videos are withheld. SHA-256 f6c4a61f8952e5b4a73fc681746da5b98c9d23a0ec0ff99a56195e8808819cf8, 1013.5 KB.
- Run ID
- 44255a11-4f64-463a-8020-b124af021fcd
- Benchmark
- lava-lamp v1
- Experiment
- Single run
- Started
- 09.11.2026 21:19 Tallinn
- Graded
- revision 1 · 09.11.2026 21:20
Works and checks, in full
All 5 blocker checks passed.
The rule: a run works when every blocker check passes. If any blocker fails it does not work. If none fails but one has no result yet, it stays pending, never counted as a pass or a fail. Extra checks are reported but do not decide it. Works is not a judgement of looks: that is the visual review.
This is a legacy contract v1 run: the task has no public requirements, and these are the original lava-lamp checks, not a versioned hidden verifier. It is never compared with contract v2 runs.
| Requirement | Check | Blocker | Result |
|---|---|---|---|
| none (v1) | Self-contained index.html is present | Blocker | pass |
| none (v1) | Visible page content | Blocker | pass |
| none (v1) | Visible autonomous animation | Blocker | pass |
| none (v1) | Accessible on/off control | Extra | pass |
| none (v1) | 390 px mobile layout has no horizontal overflow | Extra | pass |
| none (v1) | Local animation frame performance | Extra | pass |
| none (v1) | No browser errors | Blocker | pass |
| none (v1) | No attempted external or linked-resource requests | Blocker | pass |
Verification completed; eligible for benchmark results.
Visual review
Pending.
Pending: the captures have not been reviewed blind yet. Checks decide whether it works; how it looks is decided only in that review.
What ran
Requested and detected.
Detected values come from the run’s own output, never from our settings.
This run could use only file tools (read, write, edit, glob, grep): no shell.
| Field | Requested | Detected | Evidence |
|---|---|---|---|
| Model | meta/muse-ember | not reported | The harness reported no model. |
| Effort | medium | not reported | The harness reported no effort; the requested effort is shown. |
| Harness | OpenCode | opencode v2.2.6 | Version as the CLI reported it; binary SHA-256 90e4d03597b0… |
| Deadline | 60 min | 1m 30s used | Completed |
Tool decisions
Each tool call is allowed or blocked by the harness’s permission settings before it runs. Allowed is not the same as succeeded: an allowed call can still fail.
- edit2 calls · 2 accepted
- read2 calls · 2 accepted
- grep1 call · 1 accepted
- write1 call · 1 accepted
Telemetry
Time and usage.
- Generation time
- 32.2 s
- First content
- 2.2 s
- Output speed
- 439.9 tokens/s, whole run including tools
- API-equivalent cost
- $0.01 (computed from the run’s token counts at list prices, not a charge)
- Actual charge
- not reported
Input tokens
- Cache reads91,96077%
- Cache writes00%
- Uncached input27,55123%
Output tokens
- Reasoning4,22830%
- Other output9,94970%
Usage as the agent reported it at the end of the run. Cache reads are part of input; reasoning is part of output.
Transcript and source
Plain-text downloads.
The redacted transcript and the frozen output bundle, with LF line endings. Hashes are of the original files.
Redacted agent transcript: 3.0 KB, 0 redactions. Download transcript.txt
Source files
| File | Size | SHA-256 | Redactions |
|---|---|---|---|
| index.html | 24.3 KB | 4570252dbcbe40f48d6e92d703085c73784fbbd6e83faa5c65771f4aed7a620c | 0 |
Revision history
This page shows revision 1.
Grades are append-only: a regrade adds a revision and never rewrites an earlier one.
| Revision | Graded | Works |
|---|---|---|
| 1 (current) | 09.11.2026 21:20 | works |
Redaction: automated scan run; checked by Jaanus on 09.11.2026 22:10. Nothing needed redacting.