Lava lamp v1 · Claude Code · run b79ff6d9 · 09.11.2026 21:58 Tallinn
Claude Fable 5.2
Medium effortWorks
8 of 8 checks passed. All 5 blocker checks passed.
What it built: 3 captures
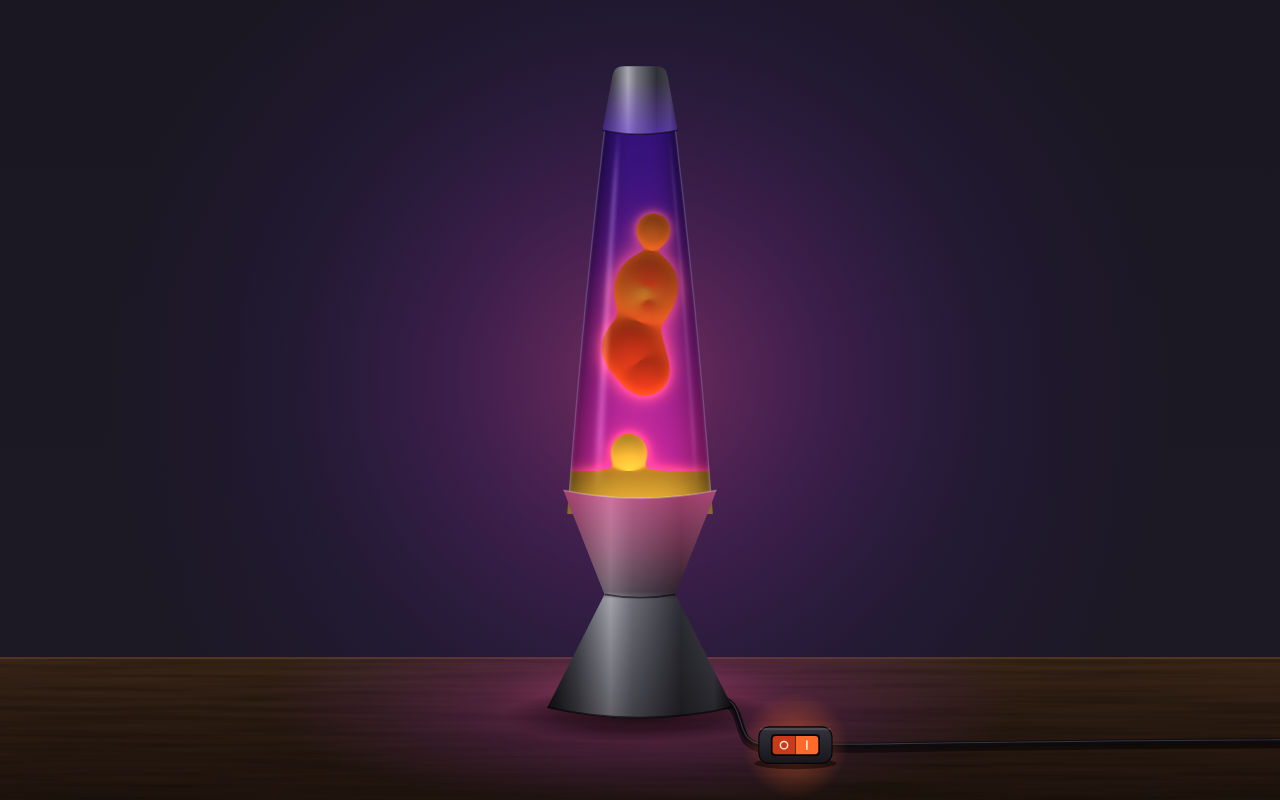
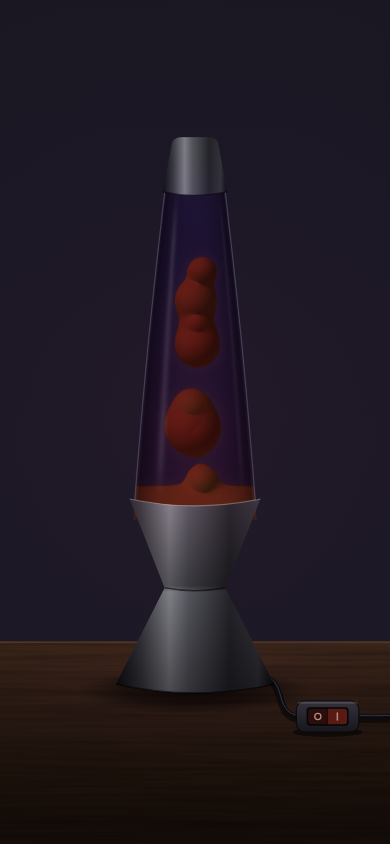
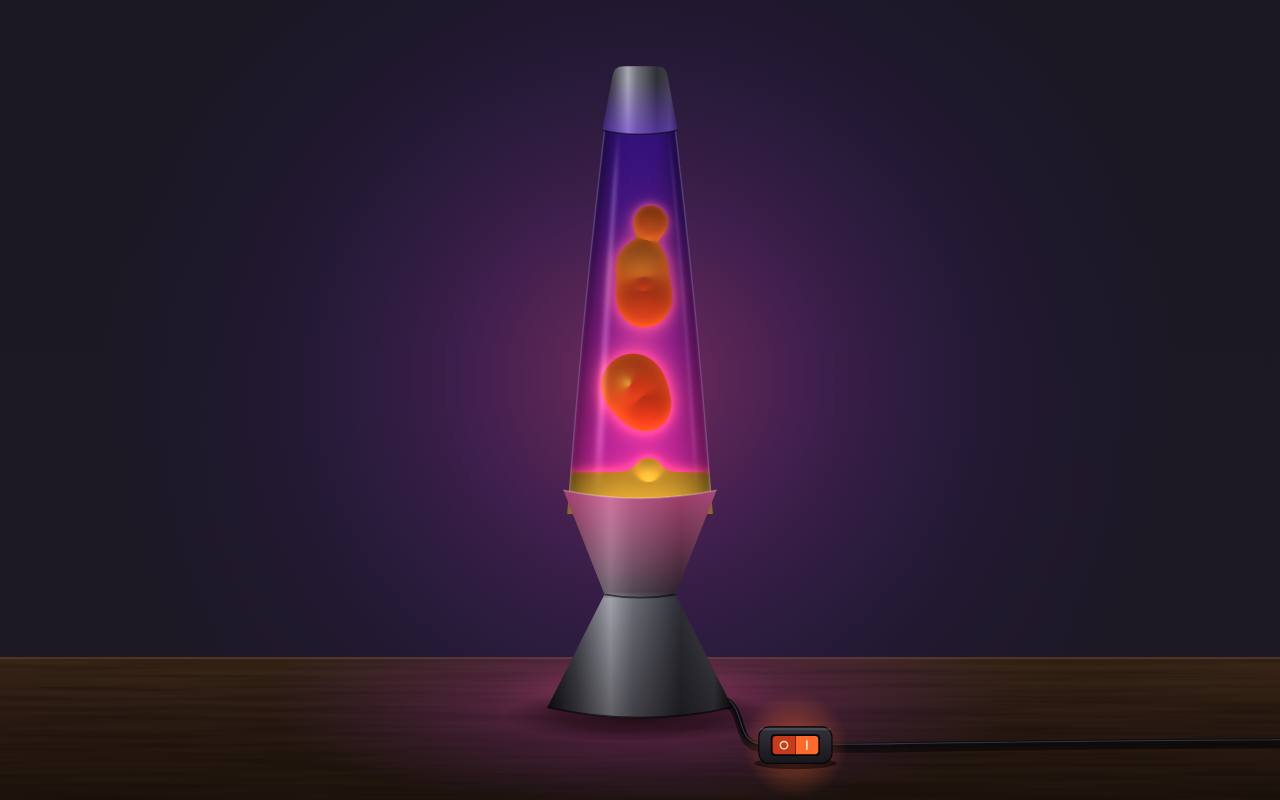
Build time
7m 47s
13th fastest of 15 models at medium effort. Wall time, start to graded: 8m 46s.
Output tokens
44,211
13th fewest of 15 models at medium effort.
Output speed
95 tok/s
8th highest of 15 models at medium effort.
API cost
$2.71
Computed from the run’s token counts at list prices, not a charge.
Along the row
Claude Fable 5.2 at every effort.
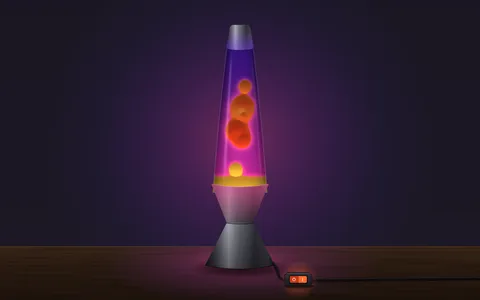
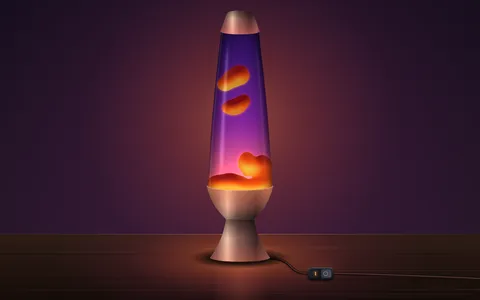
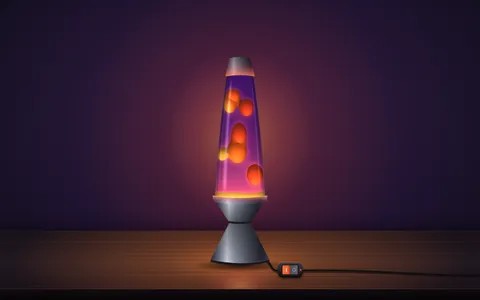
Down the column
Other models at medium effort.
Fastest median first · this run: 7m 47s
 Muse Ember32.2 s
Works
14.5× faster than this run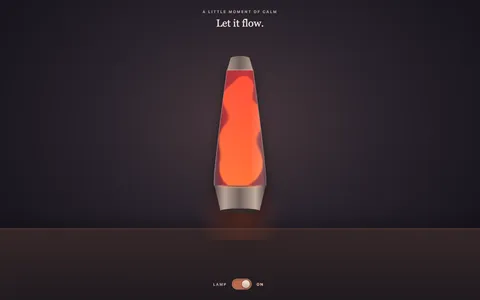 GPT-6.1 Terra47.9 s
Works
9.8× faster than this run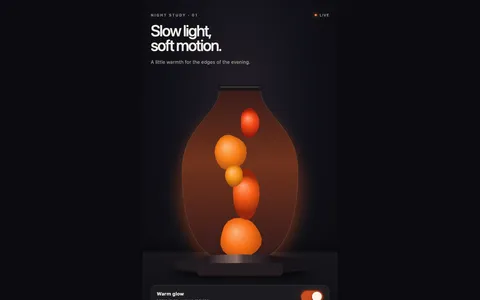 GPT-5.6 Luna59.1 s
Works
7.9× faster than this run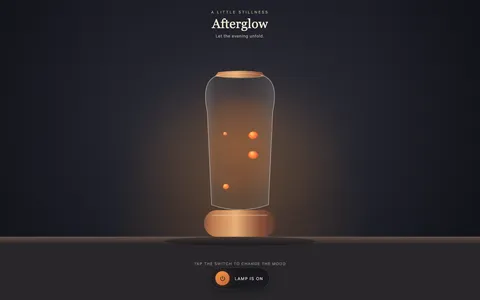 GPT-6 Luna1m 21s
Works
5.8× faster than this run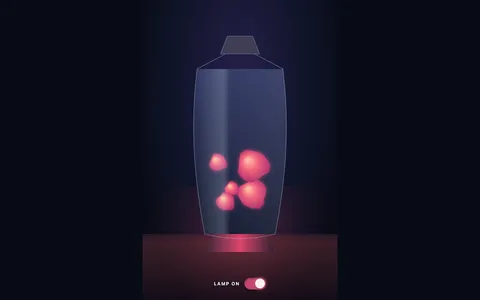 GPT-5.6 Terra1m 48s
Works
4.3× faster than this run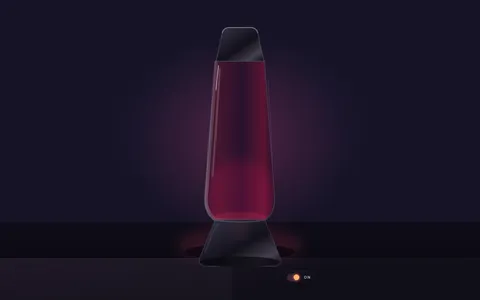 GPT-5.6 Sol2m 20s
Fails
3.3× faster than this run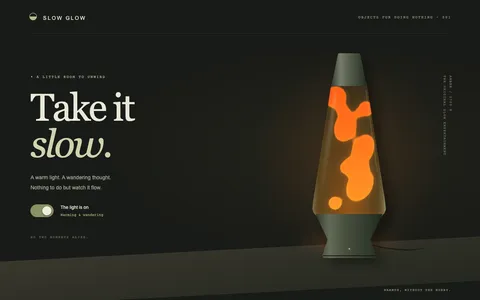 GPT-6 Astra4m 15s
Works
1.8× faster than this run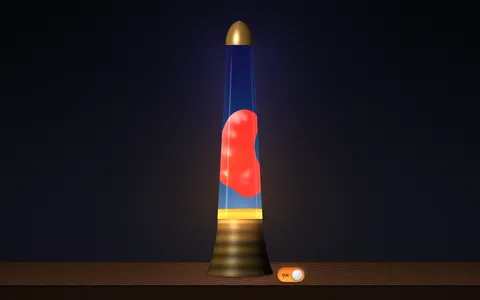 Claude Sonnet 5.54m 44s
Works
1.6× faster than this run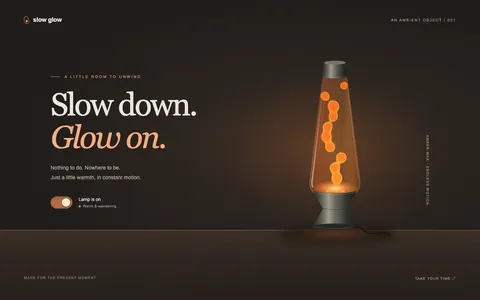 GPT-6.1 Sol4m 52s
Works
1.6× faster than this run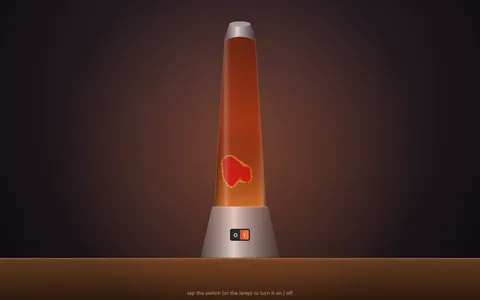 Claude Fable 5.14m 53s
Works
1.6× faster than this run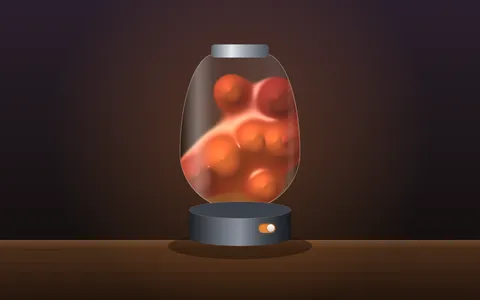 Claude Haiku 5.55m 06s
Works
1.5× faster than this run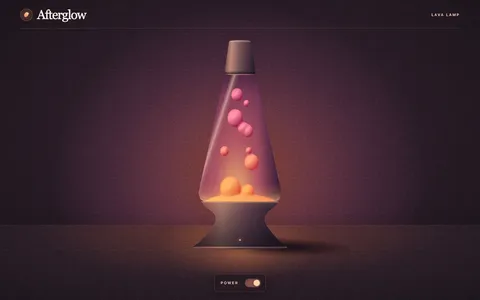 GPT-6.2 Sol7m 02s
Works
1.1× faster than this run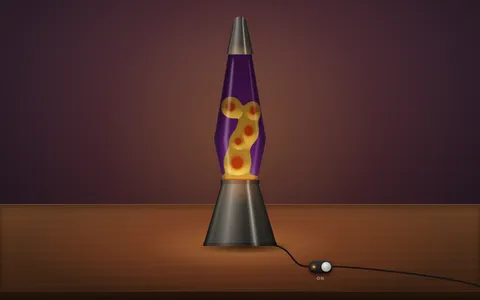 Claude Opus 5.58m 56s
Works
1.1× slower than this run GPT-6.2 Astra9m 42s
Works
1.2× slower than this run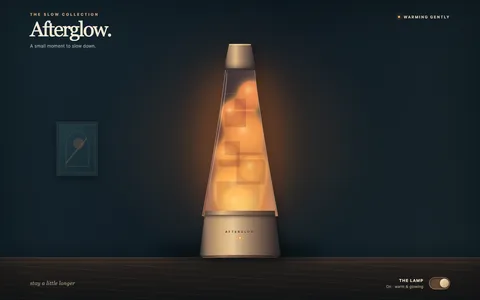 GPT-6 Sol—
Works
Hidden checks
8 of 8 checks passed.
- Self-contained index.html is presentblocker
- Visible page contentblocker
- Visible autonomous animationblocker
- Accessible on/off controlextra
- 390 px mobile layout has no horizontal overflowextra
- Local animation frame performanceextra
- No browser errorsblocker
- No attempted external or linked-resource requestsblocker
It works when every blocker passes. How it looks is reviewed blind: pending.
Run details
- Video (video): not published, videos are withheld. SHA-256 d20768c8c7fab359c38195c52e087cbaf91fafe134421fc072e95e326188b44d, 1164.8 KB.
- Run ID
- b79ff6d9-ae69-48f6-af0d-b9909af21541
- Benchmark
- lava-lamp v1
- Experiment
- Single run
- Started
- 09.11.2026 21:58 Tallinn
- Graded
- revision 1 · 09.11.2026 22:07
Works and checks, in full
All 5 blocker checks passed.
The rule: a run works when every blocker check passes. If any blocker fails it does not work. If none fails but one has no result yet, it stays pending, never counted as a pass or a fail. Extra checks are reported but do not decide it. Works is not a judgement of looks: that is the visual review.
This is a legacy contract v1 run: the task has no public requirements, and these are the original lava-lamp checks, not a versioned hidden verifier. It is never compared with contract v2 runs.
| Requirement | Check | Blocker | Result |
|---|---|---|---|
| none (v1) | Self-contained index.html is present | Blocker | pass |
| none (v1) | Visible page content | Blocker | pass |
| none (v1) | Visible autonomous animation | Blocker | pass |
| none (v1) | Accessible on/off control | Extra | pass |
| none (v1) | 390 px mobile layout has no horizontal overflow | Extra | pass |
| none (v1) | Local animation frame performance | Extra | pass |
| none (v1) | No browser errors | Blocker | pass |
| none (v1) | No attempted external or linked-resource requests | Blocker | pass |
Verification completed; eligible for benchmark results.
Visual review
Pending.
Pending: the captures have not been reviewed blind yet. Checks decide whether it works; how it looks is decided only in that review.
What ran
Requested and detected.
Detected values come from the run’s own output, never from our settings.
| Field | Requested | Detected | Evidence |
|---|---|---|---|
| Model | claude-fable-5-2 | claude-fable-5-2 | harness result, 8 of 8 API requests |
| Effort | medium | medium | 8 of 8 API requests |
| Harness | not recorded | 2.1.321 (Claude Code) | Version as the CLI reported it; binary SHA-256 abc9feeeca80… |
| Deadline | 60 min | 8m 46s used | Completed |
Tool decisions
Each tool call is allowed or blocked by the harness’s permission settings before it runs. Allowed is not the same as succeeded: an allowed call can still fail.
- Bash7 calls · 6 accepted · 1 rejected · 6 failed
- Edit6 calls · 6 accepted
- Write2 calls · 2 accepted
Telemetry
Time and usage.
- Generation time
- 7m 47s
- First content
- 1.0 s
- Output speed
- 94.6 tokens/s, whole run including tools
- API-equivalent cost
- $2.71 (computed from the run’s token counts at list prices, not a charge)
- Actual charge
- not reported
Input tokens
- Cache reads342,94686%
- Cache writes54,45014%
- Uncached input16<0.1%
Output tokens
- Reasoning25,62358%
- Other output18,58842%
Usage as the agent reported it at the end of the run. Cache reads are part of input; reasoning is part of output.
Transcript and source
Plain-text downloads.
The redacted transcript and the frozen output bundle, with LF line endings. Hashes are of the original files.
Redacted agent transcript: 56.0 KB, 13 redactions. Download transcript.txt
Source files
| File | Size | SHA-256 | Redactions |
|---|---|---|---|
| index.html | 25.8 KB | e81e1a47d1c06ed54be42556437b30bdb686e68746542f8c605c284bfcc9d0ce | 0 |
Revision history
This page shows revision 1.
Grades are append-only: a regrade adds a revision and never rewrites an earlier one.
| Revision | Graded | Works |
|---|---|---|
| 1 (current) | 09.11.2026 22:07 | works |
Redaction: automated scan run; checked by Jaanus on 09.11.2026 22:10. Redacted: 4 local-path, 3 user-path, 6 username.